
Why i can't enjoyably use AI model on my mac
Hey it's not only me, it's you too, we are dependent on cloud based llm provider to for everything AI, no privacy and a lot of restrictions,
Like you can't do deep AI research with claude opus (it against their usage policy go figure), last week Anthropic quietly made dropped an update on claude code to refuse when users try clone games with the popular REA AI skill, they are several restrictions you may have faced as well.
Well enough rant, What is NCM?
The biggest bottleneck of running top open models locally is memory bandwidth and sadly the ram costs are off the roof, if there's still a roof, sam altman wants your pc ram for his data centre btw.
A fascinating new research paper out of Stanford University proposed an architecture called Next Concept Modeling (NCM), and if it holds up to the test, it could turn our current reliance on hyper-expensive memory chips into a bad investment, for what its worth, i don't think current AI investment are 100% secured against these kinds of innovations, but this is just my opinion.
Why Token-by-Token is bottlenecked
To understand why this is such a big deal, you have to look at how the AI models we use today actually function.
Todays top LLM as a very sophisticated and incredibly slow. When you ask it to write a 1,000 word response, it doesn’t just spit out the text out in one go. Instead, it generates a single token, a small fragment of a word and then it has to pause, process everything, and repeat the entire sequence for the next one.
By the time that model has finished a 1,000 word response, it has essentially performed 1,000 separate passes through its own massive parameter list.
Every single one of those passes requires the GPU to pull data from its video memory. As context windows grow, the KV cache starts to grow exponentially.
It eats up available memory like hot pepper, creating a hardware bottleneck that makes these models incredibly slow and expensive to run locally btw.
NCM: Okay we need to Think in Layers, Not Tokens?
The team at Stanford wants to ditch this linear, token-by-token and instead, they looked at how image diffusion models actually work.
Think about how diffusion models (like Midjourney or Stable Diffusion) generate an image: it doesn’t draw pixel-by-pixel from top to bottom like an old printer, it dumps a whole blurry noisy canvas all at once, and then iteratively sharpens the details layer by layer until everything looks crisp.
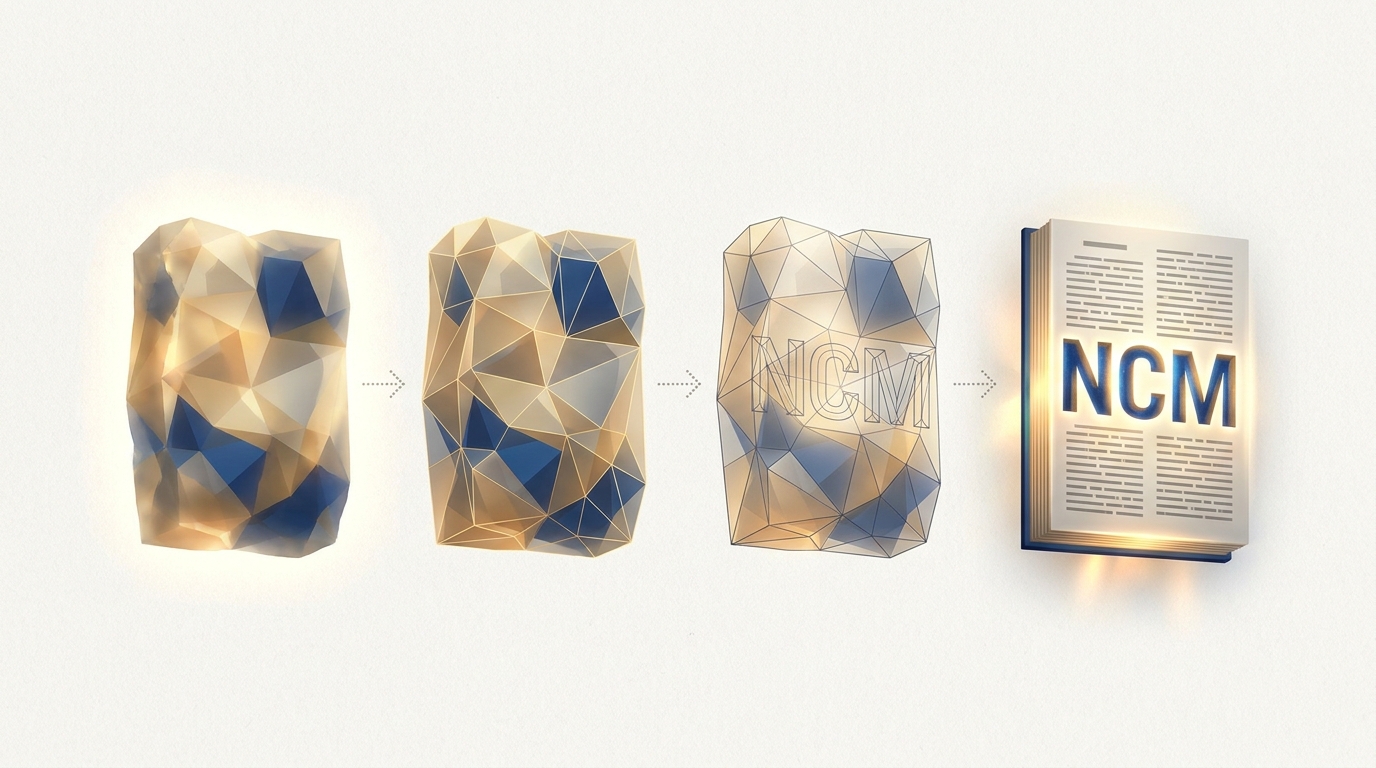
That's pretty much what NCM is doing for text. When you prompt an NCM model, it spits out the whole response in parallel across a series of layers. The top layer handles the broad concept and raw skeleton of what to say, while the subsequent layers refine those concepts into actual words and sentences, more like diffusion if you will agree with me.
Because of this parallel structure, where a traditional model might take 1,000 passes to write a response, an NCM model can achieve the same result in just 32 passes. That’s like a 30x boost in runtime, which is pretty wild.
Hallucination is still an headache if it will
Doing everything in parallel comes with its own set of headaches though. How do you stop a model from just guessing? How do you ensure it actually understands the concept rather than just outputting compressed noise? The researchers baked three clever tricks into the NCM architecture to solve these which is i find very interesting, find out below!
1. Nested Dropout, (kill dead weights after grokking)
During training, the researchers would randomly drop the lower, more detailed layers completely. Think about it: if the top layer knows the detail layers might get ripped away, it can't just be lazy and rely on the specifics to save it at the end. It’s forced to actually grok and encode genuine understanding right in its top-level layers before passing anything down.
2. Conditioning Corruption
One of the biggest issues with a layer-based system is that a mistake in the first layer will ripple down, causing a complete "error death spiral."
To prevent this from wrecking everything, the team did something wild called conditioning corruption. They deliberately injected wrong information into the middle layers during training. This taught the model to recognize when things are starting to go off-balance and, more importantly, how to self-correct back to the right path instead of hallucinating into oblivion.
3. Test-Time Scaling
Because NCM generates text so fast, the system can spit out 20 different candidate answers in the same time it would take a traditional model to write one. It then runs a consensus check using a filter known as Minimum Bayes Risk (MBR) to find the most solid answer among those 20 candidates. You basically get better reasoning without the brutal wait time.
Dollars and how it's now preserved
The Stanford paper is one of the torch showing us what is ahead. Right now, the AI industry is tied to massive memory bandwidth architecture to keep that KV cache running. If we can shift that bottleneck from memory to raw compute, the people playing in the field changes entirely, i mean big win for local AI use.
Imagine you don’t need the most expensive NVIDIA GPU just to run a capable model. If NCM scales, we could see frontier-level AI performance on consumer grade hardware.
But obviously, there is no free lunch
The parallel layers require more raw processing power, and we still need to see if this architecture holds up when we move from smaller tests to massive, trillion-parameter models. But it definitely serves as a wake-up call to the industry.
The current path isn’t the only path. Our hardware limits aren't laws of physics; they're just design choices. And if a single paper from Stanford is any indication, the future of AI might be way more efficient than we do think.
Now i have a question for you, "What is a NCM with your understanding so far?"
Original Stanford paper: https://arxiv.org/html/2610.14162v1